In an aggressive bid to defend its consumer footprint against rapidly escalating international competition, OpenAI has officially recalibrated its platform economics. The company announced that its newly unveiled GPT-5.6 Luna model will now serve as the default engine for all free and entry-level tiers, eliminating traditional message frequency caps on standard text conversations. Simultaneously, ChatGPT crossed the milestone of one billion weekly active users, transforming what was once an experimental consumer interface into one of the most heavily trafficked distributed computing utilities in history.
Architectural Distinctions in the GPT-5.6 Generation
The GPT-5.6 model family bifurcates into distinct operational branches designed to optimize server-side compute expenditure against task complexity. GPT-5.6 Sol functions as the heavy lifting engine dedicated to ChatGPT Plus and enterprise tiers, boasting a 68 percent reduction in factual hallucinations compared to the prior GPT-5.5 Instant baseline. Sol incorporates granular compute steering via an interface slider, allowing corporate and research users to scale the latent reasoning budget allocated to a given prompt.
The Mechanics of On-Demand Test-Time Compute
Perhaps the most significant mechanical addition to the free user experience is the introduction of a dedicated interface control labeled simply as the Think button. Historically, modern reasoning architectures have either automatically engaged long internal reasoning traces—consuming massive amounts of GPU cluster capacity—or relied on standard autoregressive sampling that frequently falters on complex spatial, mathematical, or algorithmic problems. The new control transfers the scheduling switch directly to the user.
When an operator engages the Think mechanism, GPT-5.6 Luna switches into a dynamic inference loop, spending measurable extra compute cycles generating, critiquing, and pruning internal chain-of-thought search trees prior to emitting output tokens. This decoupling of baseline inference from intensive problem-solving solves a critical logistical conundrum for cloud providers. By letting users dictate when deep reasoning is genuinely required, OpenAI prevents its clusters from burning compute cycles reasoning through trivial queries like email drafting or basic translation.
From an algorithmic standpoint, this represents an expansion of test-time scaling down to zero-dollar consumer accounts. System telemetry can dynamically route queries that request deeper deliberation to specialized server pools equipped with higher memory bandwidth, while everyday latency-sensitive queries remain pinned to high-throughput, low-precision inference nodes. This flexible tiering is crucial for maintaining real-time responsiveness across thousands of concurrent enterprise workloads sharing physical data center resources.
The Brutal Physics of One Billion Weekly Active Users
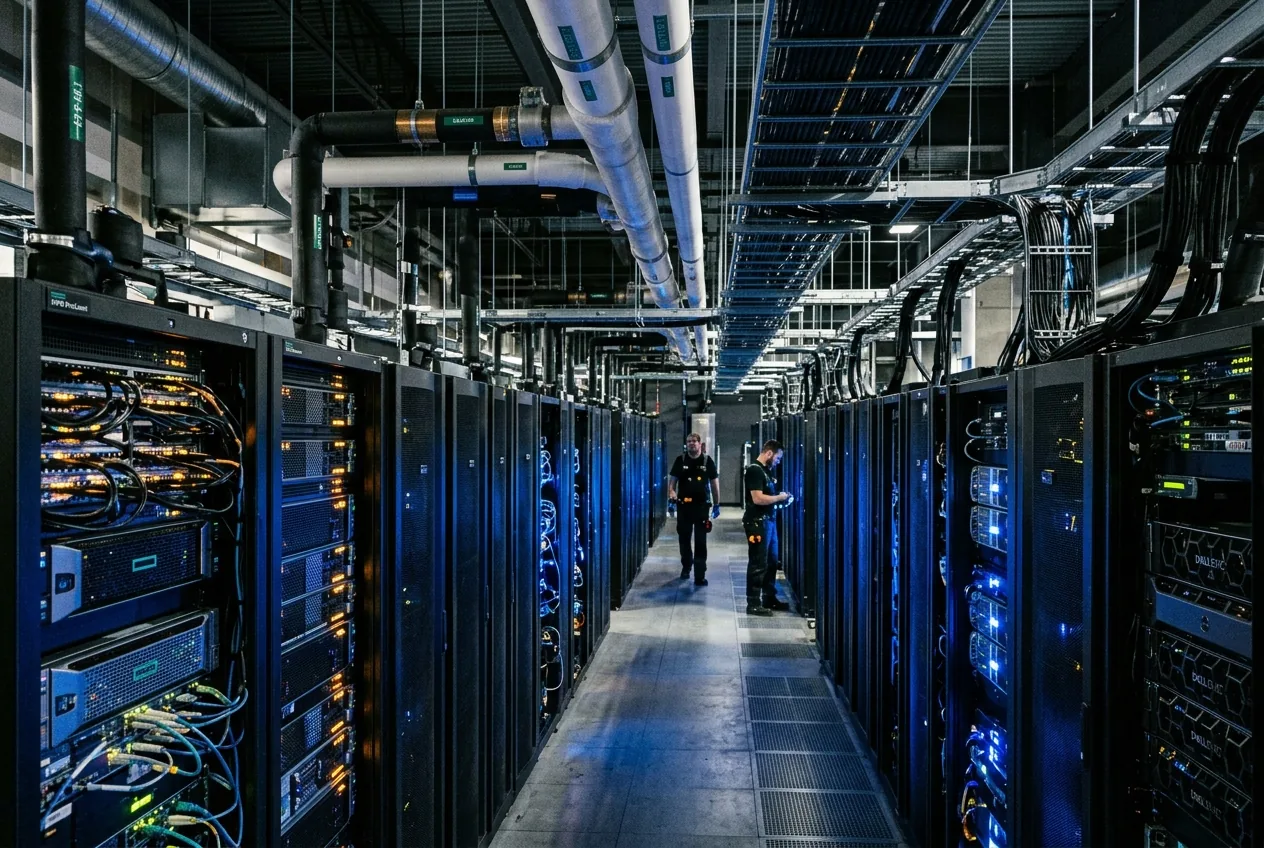
Operating a conversational platform that serves a ten-figure user base weekly introduces mechanical and thermal bottlenecks that dwarf conventional web-scale architectures. Traditional software services consume nominal CPU cycles per pageview, primarily managing database transactions and edge caching. Large language model inference, however, requires continuous, highly synchronized matrix multiplications across interconnected tensor processing arrays, demanding unrelenting electrical power and advanced liquid-to-air thermal exchange systems.
Lifting chat limits entirely suggests that OpenAI and its cloud partners have achieved breakthrough operational efficiencies in their silicon deployment. The transition involves aggressive deployment of low-precision quantization formats, such as FP8 and sub-8-bit floating point matrix math, without destabilizing attention mechanisms. Furthermore, improvements in speculative decoding—wherein a hyper-efficient draft model speculates several tokens ahead while the primary model verifies them in parallel—have drastically compressed the wall-clock time required to generate each user response.
Without these hardware-level and runtime optimizations, the capital expenditure required to absorb infinite conversational loops from hundreds of millions of unmonetized users would be ruinous. The hardware footprint required to serve one billion weekly users cannot be sustained on commercial software license revenues alone. It demands unprecedented amortization of silicon infrastructure, relying on sheer scale to depress unit costs across every million tokens delivered.
Can Closed Platforms Withstand the Open-Weights Pressure?
The broader catalyst behind OpenAI’s sudden generosity is the shifting tectonic plate of global generative AI supply chains. Over the past twelve months, Chinese tech conglomerates and agile research labs have systematically commoditized baseline conversational intelligence. Models operating with hundreds of billions of parameters have been released with permissive open-source licenses, providing enterprise-grade coding, mathematics, and translation capabilities to local machines and private clouds at a fraction of Western commercial API prices.
This surge of open models has fundamentally altered enterprise leverage. Small-to-medium software operations, manufacturing firms, and automation engineers are no longer forced to integrate proprietary American APIs when self-hosted, highly performant alternatives can run inside on-premise hardware clusters. In regions outside North America, where regulatory compliance, data sovereignty, and hardware import restrictions dictate technology roadmaps, local open-source models have gained rapid enterprise adoption.
Industrial Utility and the Pathway to Physical Automation
While consumer attention focuses on text interfaces, the real battleground for models boasting a 62 to 68 percent drop in factual errors lies in automated industrial pipelines. In industrial robotics, computer vision coordination, and automated logistics networks, synthetic intelligence has long been restricted by latency, unpredictability, and catastrophic hallucinations. An error in an administrative document is inconvenient; an error in a robotic path-planning program or an inventory supply script can shut down a manufacturing line or damage mechanical assets.
The refinement of reasoning architectures directly feeds into the execution of agentic workflows. When foundation models can be trusted to reason through multi-step mechanical assembly instructions, parse complex blueprints, or translate structured sensor streams into deterministic control inputs, the boundary between generative text processing and cyber-physical automation disappears. The operational improvements demonstrated in the GPT-5.6 generation provide the baseline reliability required for integration into programmable logic controllers, warehouse management software, and edge computing nodes operating on factory floors.
Ultimately, OpenAI’s transition to an unlimited-access framework marks the end of the initial scarcity phase of artificial intelligence. As the global race between Western commercial labs and international open-source development intensifies, the primary barrier to entry is no longer the ability to run a model—it is the engineering capability to scale distributed compute reliably, affordably, and accurately across an entire planet of users demanding continuous intelligence.




Comments
No comments yet. Be the first!