Frontier artificial intelligence development has reached a threshold where silicon throughput and algorithmic design are no longer the sole determinants of a model release date. The deployment of OpenAI's GPT-5.6 series marks an inflection point in how cutting-edge foundation models transition from training clusters into commercial reality. Rather than shipping immediately following reinforcement learning checkpoints, the new model family underwent an extended, formal vetting period conducted in coordination with the United States Artificial Intelligence Safety Institute and related federal bodies. This formal audit signals a permanent shift toward institutional pre-deployment certification for frontier cognitive systems.
For enterprise engineers and industrial systems architects, the arrival of GPT-5.6 represents far more than an incremental bump in benchmark scorecards. The release demonstrates a deliberate recalibration of compute allocation, moving beyond raw conversational fluency toward deterministic reasoning, long-horizon operational execution, and low-latency interaction with physical infrastructure. OpenAI has packaged the architecture into distinct tiers engineered to handle both heavy enterprise reasoning and edge-adjacent industrial orchestration, setting a baseline for how multi-agent systems interact with complex physical workflows.
The Anatomy of Federal Clearance
The operational delay preceding the public rollout of GPT-5.6 highlights the expanding scope of statutory and voluntary governance over frontier computing. Evaluators from the U.S. Artificial Intelligence Safety Institute, operating under frameworks established by the National Institute of Standards and Technology, subjected the model weights to extensive red-teaming protocols. Unlike earlier safety evaluations that primarily screened for toxic outputs or conversational bias, the scrutiny applied to the 5.6 architecture prioritized dual-use national security risks, automated exploitation capabilities, and autonomous replication tendencies.
Technical reviews focused heavily on the model's ability to interface autonomously with networked industrial control systems and software supply chains. Assessors audited the model's capacity to synthesize zero-day cyber exploits, analyze air-gapped SCADA system configurations, and execute complex logic injection into programmatic controllers. The release was authorized only after OpenAI demonstrated verifiable mechanistic guardrails, including run-time circuit breakers that monitor intermediate reasoning traces when the model processes low-level machine code, network telemetry, or biochemical data structures.
This compliance cycle establishes an operational precedent for tier-one artificial intelligence labs. The clearance protocol demonstrates that future leaps in foundation model performance will be governed by standardized validation pipelines analogous to aerospace airworthiness certifications or pharmaceutical efficacy trials. For industrial operators eyeing autonomous systems, this layer of regulatory clearance provides a degree of institutional assurance that has previously been absent from commercial deployments.
Architectural Refinements in the 5.6 Core
Beneath the governance framework lies a substantially re-engineered architecture. The GPT-5.6 generation departs from monolithic scale-up philosophies, leaning aggressively into dynamic sparse Mixture-of-Experts routing coupled with integrated test-time compute scaling. While OpenAI maintains its standard proprietary reticence regarding precise parameter tallies, telemetry data and system throughput indicate that the core model activates only a fraction of its total parameter base per forward pass, drastically reducing memory bandwidth constraints during inference.
Context length has been expanded alongside improvements in retrieval fidelity. The model maintains coherent state tracking across hundreds of thousands of tokens, resolving long-standing issues surrounding intermediate state degradation in complex operational logs. In practical benchmarks, GPT-5.6 demonstrates a near-linear retention profile across extended operational windows, ensuring that temporal sensor feeds, extensive API documentation, and historical telemetry data can be evaluated simultaneously without catastrophic forgetting.
Translating Digital Reasoning to Physical Industry
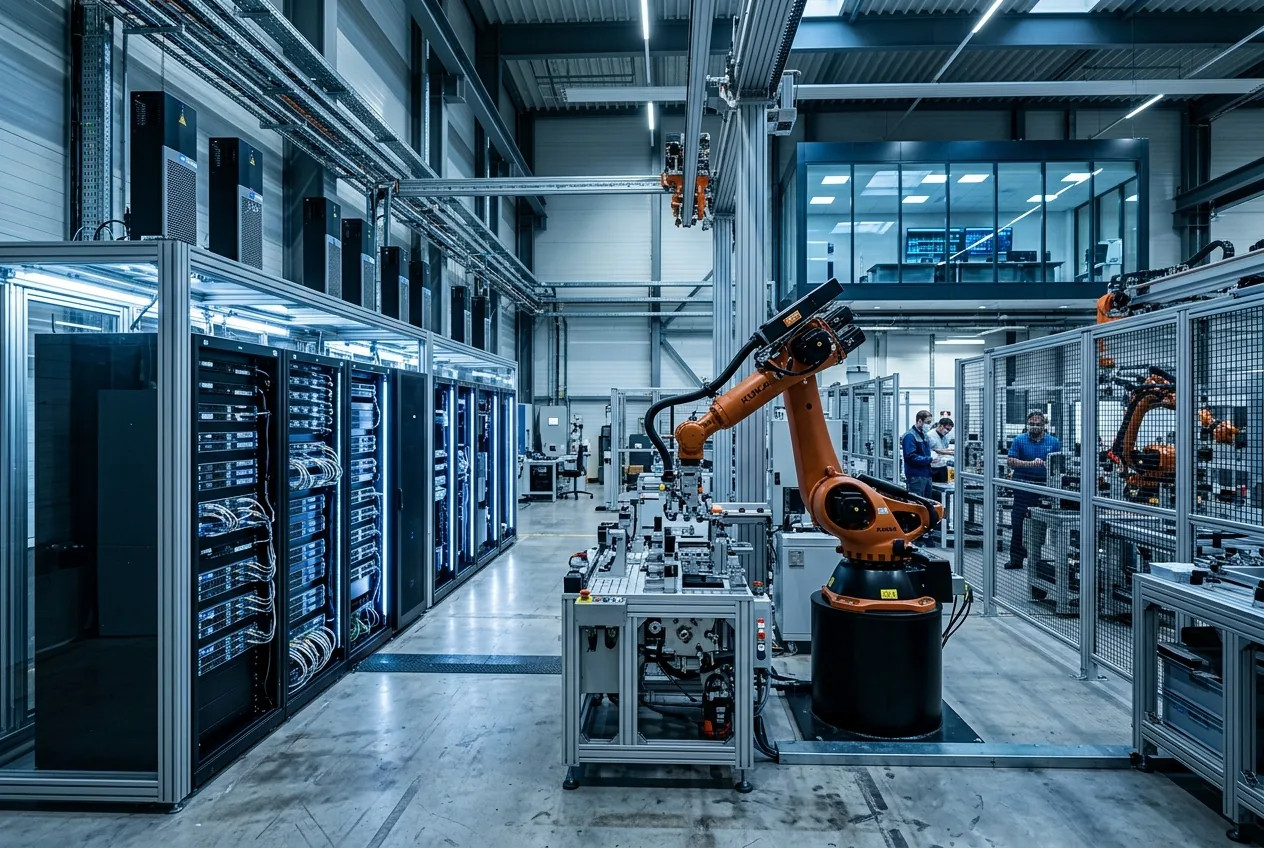
The true test of GPT-5.6 does not reside in generic linguistic benchmarks; it lives in its applicability to mechanical systems, programmable logic controllers, and automated physical operations. Previous generations of large language models functioned primarily as advisory interfaces, offering suggestions that human operators translated into mechanical execution. GPT-5.6 bridges this divide by providing highly structured, deterministic output profiles tailored for integration with robotics middlewares like ROS 2 and legacy industrial protocols like Modbus and OPC UA.
This capacity drastically reduces the overhead traditionally associated with industrial re-tooling. In agile manufacturing environments where production lines must adapt to low-volume, high-mix component runs, programming conventional industrial manipulators has historically required dozens of engineering hours. GPT-5.6 can ingest three-dimensional CAD geometries, cross-reference assembly specifications, and generate robust, validated robot motion primitives in minutes, fundamentally altering the economics of flexible manufacturing.
Compute Economics and Operational Costs
While the architectural capabilities are formidable, the enterprise calculus surrounding GPT-5.6 hinges on unit economics and inference expenditure. Frontier models frequently impose prohibitive operational expenditures when integrated into high-frequency data pipelines. OpenAI has addressed this friction by introducing an aggressive tiered quantization and distillation hierarchy, enabling enterprise customers to deploy smaller, model-distilled derivatives directly on premise or at the industrial edge.
The flagship variant of GPT-5.6 remains cloud-bound, consuming massive cluster bandwidth across liquid-cooled accelerator arrays. However, its edge-optimized counterparts demonstrate remarkable fidelity retention, running on modest industrial inference hardware located directly within factory perimeters. This edge-tier capability mitigates the dual vulnerabilities of WAN latency and proprietary data exfiltration, allowing manufacturing facilities to process vision streams and machinery health data locally while reserving deep reasoning queries for central cloud instances.
Furthermore, OpenAI's optimization of speculative decoding and key-value cache compression has driven down the cost-per-million-tokens for high-volume batch processing. In predictive maintenance contexts, where thousands of machine vibration profiles and thermal sensor readings must be processed continuously, the operational cost of continuous monitoring has dropped sufficiently to justify continuous autonomous oversight over high-value capital assets.
The Emerging Paradigm of Certified Machine Intelligence
The deployment of the GPT-5.6 series represents the closing of an experimental era and the maturation of artificial intelligence into critical infrastructure. The convergence of federal oversight, architectural specialization, and industrial compatibility indicates that the sector is leaving behind unconstrained consumer experimentation in favor of enterprise-grade durability. AI systems are evolving into structural components of national productivity, subject to the same rigorous safety tolerances as power grids and civil transit networks.



Comments
No comments yet. Be the first!