In an ecosystem where inference compute has historically dictated hard rate caps and metered access, the operational mechanics of consumer artificial intelligence are undergoing a fundamental recalibration. OpenAI has removed its long-standing text chat caps for free-tier users while rolling out its GPT-5.6 model family across consumer and enterprise interfaces. The deployment introduces two distinct system tiers: GPT-5.6 Luna, a streamlined model engineered for high-throughput public deployment, and GPT-5.6 Sol, a consolidated reasoning engine designed for paid subscriptions.
The structural change is significant. Free-tier users—an audience OpenAI now estimates at roughly one billion weekly active individuals—will transition to GPT-5.6 Luna, shedding the restrictive rate quotas that previously halted long-form conversations. Concurrently, paid Plus and Pro tiers are transitioning away from separate conversational and reasoning engines in favor of a single unified pipeline. By collapsing instant generation and chain-of-thought deliberation into a dynamically scalable system, the release illustrates how advances in test-time compute scaling and architectural distillation are reshaping the economics of serving large language models at planetary scale.
The Economics of Dropping Inference Caps
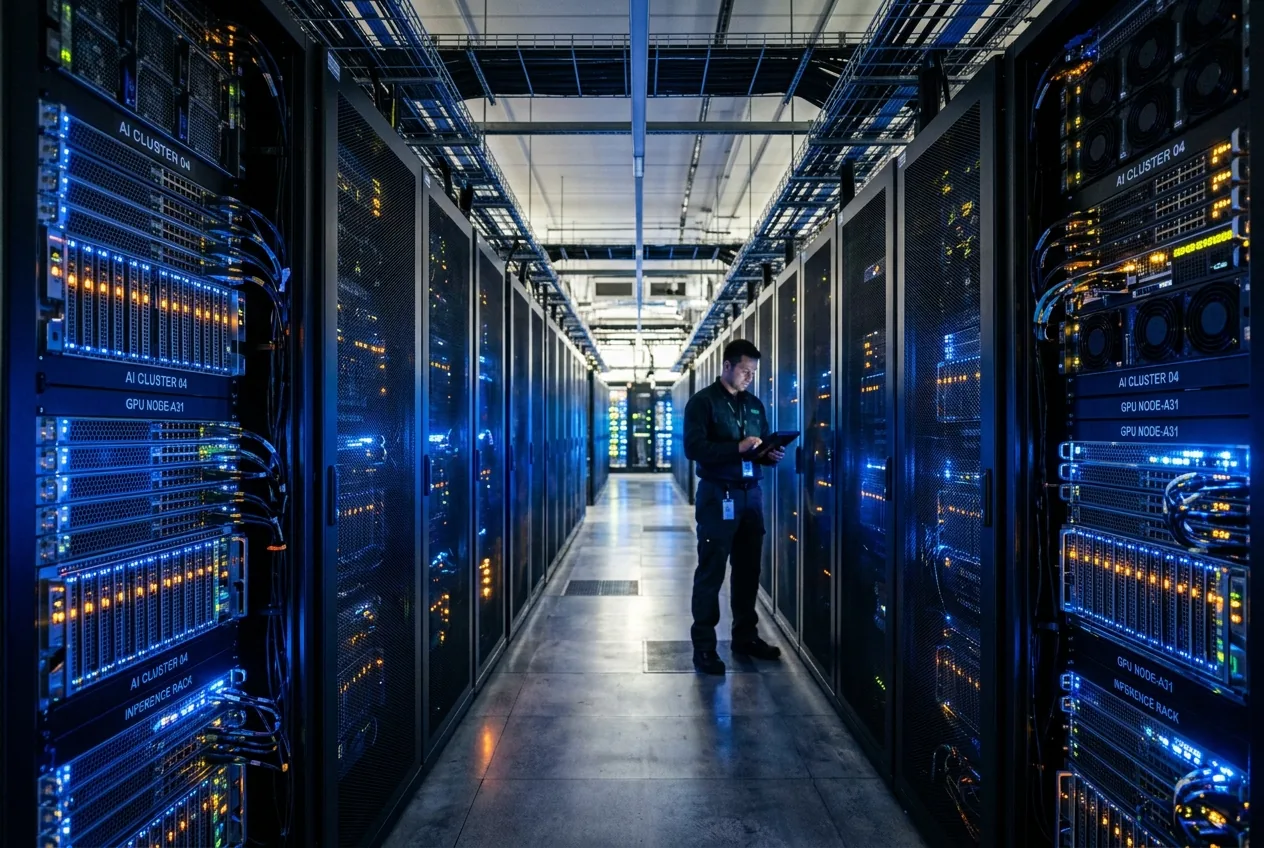
For data center operators and machine learning infrastructure engineers, lifting rate caps across a user base of one billion weekly visitors is not merely a product decision; it is a massive logistical undertaking. Generating tokens at this magnitude requires astronomical floating-point operations per second (FLOPs). Up until this release, strict usage throttles acted as load-shedding mechanisms, shielding underlying GPU and accelerator clusters from peak concurrency spikes during high-demand windows.
Crucially, the operational boundaries remain strictly compartmentalized. While basic alphanumeric conversational bandwidth is now unlimited, OpenAI has preserved strict rate throttling on resource-intensive modalities. High-overhead features, including image synthesis, file ingestion, automated code execution, and real-time bidirectional voice streams, remain gated behind quotas and subscription walls. From an infrastructure perspective, this preserves precious high-bandwidth memory and heterogeneous compute resources for higher-margin operations while leveraging highly optimized matrix multipliers for base text generation.
Collapsing Deliberation and Speed into GPT-5.6 Sol
While Luna tackles the volumetric demands of the public consumer tier, GPT-5.6 Sol introduces a critical technical shift in how high-parameter systems handle reasoning tasks. Historically, frontier artificial intelligence platforms required users to manually select their operating paradigm: an optimized 'instant' model for rapid, low-latency dialogue, or a dedicated 'reasoning' engine that spent prolonged processing cycles synthesizing step-by-step rationales prior to emitting a final answer.
Sol collapses this operational dichotomy into a single model. Rather than requiring parallel model checkpoints or routing requests across disparate neural network weights, Sol incorporates variable test-time compute directly into its internal decoding strategy. This unified architecture allows the model to adjust its latent processing depth based on task complexity or explicit user steering. Users can now manipulate an integrated reasoning slider to adjust compute allocation dynamically, deploying shallow token exploration for routine drafts and deep, iterative self-correction paths for complex logic synthesis, financial forensics, or software architecture.
This consolidation yields tangible efficiency advantages across enterprise workflows. In complex multi-turn interactions, maintaining separate context caches across different reasoning and instant models introduced significant latency penalties and memory fragmentation. By utilizing a single set of weights capable of modulating its own computational budget on demand, context states remain persistent in the Key-Value (KV) cache, minimizing recomputation overhead and system-level context switching.
Benchmarking Reliability in High-Stakes Domains
Historically, aggressive distillation and model pruning have carried an unwelcome side effect: degraded factuality and elevated hallucination rates. Because conversational models optimize for the next most probable token rather than verified external reality, reducing compute footprint often exacerbated epistemic unreliability. Internal benchmarking data released alongside GPT-5.6 indicates that OpenAI has targeted this vulnerability directly through improved alignment and structured reasoning verification.
Across rigorous evaluation suites spanning medicine, financial compliance, and legal statutory interpretation, the GPT-5.6 family demonstrates marked improvements in factual consistency. In comparative testing against GPT-5.5 Instant, GPT-5.6 Sol reduced factual errors by 68 percent, while the lightweight Luna architecture recorded a 62 percent reduction in inaccurate outputs. These reductions reflect more rigorous reinforcement learning from human and automated feedback (RLHF/RLAIF), paired with automated checking routines that evaluate intermediate deduction steps before token emission.
The Strategic Divergence Across Enterprise and Public Systems
The strategic deployment of GPT-5.6 also illuminates OpenAI’s increasingly bifurcated development roadmap. While Luna and Sol roll out across cross-platform consumer environments on web, desktop, and mobile, OpenAI explicitly clarified that enterprise environments—specifically ChatGPT Work and Codex—will operate under isolated maintenance lines decoupled from this immediate consumer update.
This bifurcation highlights the distinct engineering constraints governing consumer platforms versus high-assurance industrial toolchains. In enterprise software development and industrial automation, deterministic behavior, immutable API contracts, and consistent latency are paramount. Rolling out architectural revisions with dynamic reasoning sliders can inadvertently disrupt automated pipelines, Continuous Integration (CI) test suites, and strict Service Level Agreements (SLAs). Consumer interfaces, conversely, benefit immediately from adaptive latency and crowd-sourced stress-testing.
The Long-Term Trajectory of Test-Time Scaling
The arrival of the GPT-5.6 generation points toward a broader industry transition away from pure pre-training scaling laws toward inference-time compute optimization. As physical datacenter footprints encounter thermal, electrical, and fabrication constraints, simply scaling the parameter count of monolithic models yields diminishing marginal utility. The primary lever for performance gains has pivoted toward the smart distribution of cycles during the inference phase.
As these models propagate across daily consumer hardware and industrial workflows, the technical focus moves toward perfecting the runtime control systems that manage them. Balancing dynamic latency against factual rigor remains the central operational challenge of the current generative era. With GPT-5.6, the industry catches a glimpse of an operational future where systems do not merely output predictions at a constant rate, but deliberately regulate their own cognitive latency to match the engineering complexity of the task at hand.




Comments
No comments yet. Be the first!