The iteration cycles governing frontier artificial intelligence have compressed from years into mere weeks. Inside OpenAI, preparations have accelerated for the rollout of GPT-5.6, an interim flagship model positioned as a direct upgrade to the GPT-5.5 architecture deployed just months earlier. Chief scientist Jakub Pachocki framed the model internally as a meaningful performance leap, signaling that engineering teams are wringing deeper efficiencies and sharper synthetic reasoning out of existing cluster footprints. Yet the technical release does not exist in an academic vacuum. It arrives alongside a confidential filing for an initial public offering with the Securities and Exchange Commission, thrusting OpenAI into an unprecedented collision between cutting-edge computational research and the exacting balance-sheet demands of public equity markets.
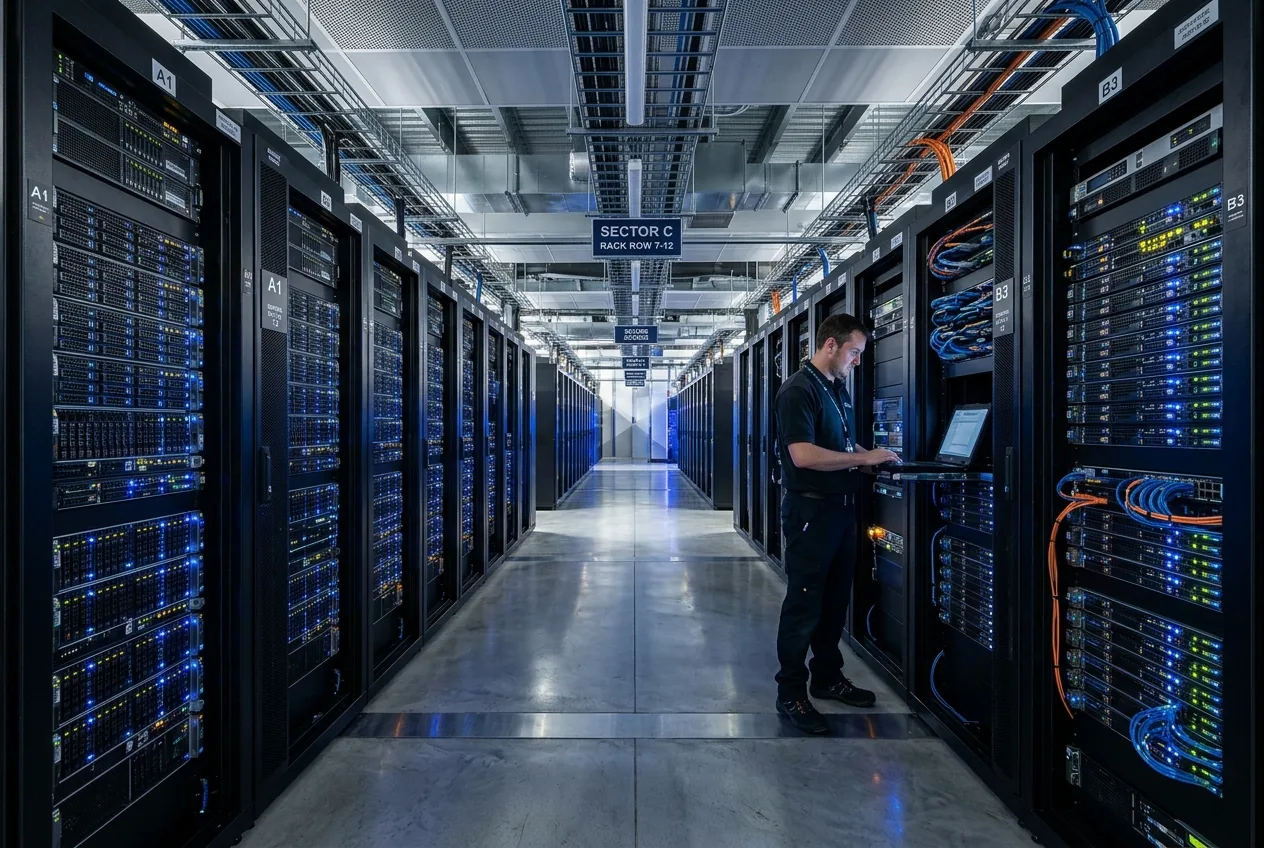
For enterprise infrastructure engineers and market observers alike, the timing illustrates the mechanical discipline now required to sustain frontier labs. OpenAI is balancing massive infrastructure overhead against a user base exceeding 900 million weekly active participants and a monthly revenue run rate hovering around $2 billion. To command a public market valuation approaching $852 billion or more, the company can no longer rely on sporadic generational breakthroughs. Instead, it must demonstrate a predictable industrial cadence: steady inference cost reductions, higher task-completion fidelity, and continuous delivery of specialized domain models that enterprise customers can integrate directly into production workflows.
The Engineering Logic of Incremental Flagship Deployments
The push toward GPT-5.6 reflects a foundational shift in how large-scale model architectures are engineered, refined, and served. During earlier phases of the deep learning boom, laboratories prioritized raw parameter scaling during pre-training, resulting in massive, monolithic jumps between whole-number model versions. Today, the frontier has largely bifurcated into post-training optimization, algorithmic pruning, and multi-stage test-time compute. Improvements between fractional iterations like 5.5 and 5.6 hinge heavily on synthetic data curation, process-supervised reward modeling, and tighter alignment loops that minimize hallucinatory drift without exploding token latency.
Furthermore, deploying an intermediate flagship preserves precious capital. Training a multi-trillion-parameter base model from scratch demands extraordinary power allocations and dedicated clusters of high-bandwidth memory accelerators. In contrast, intermediate iterations leverage checkpoint distillation, specialized continuous pre-training, and reinforcement learning on verifiable domains like software compilation and symbolic logic. This pipeline yields higher task efficiency per watt, providing end users with superior reasoning capabilities while suppressing the token-generation cost curve for the host infrastructure.
Inference Economics and the Realities of Public Scrutiny
Transitioning from a privately funded venture vehicle into a publicly traded corporation fundamentally alters the physics of software economics. In private rounds, venture syndicates routinely subsidize heavy gross margin deficits to capture sovereign market share and compute capacity. Public market institutional investors operate on entirely different metrics: gross margins, compute return on investment, capital expenditure depreciation cycles, and customer acquisition payback periods. For OpenAI, projecting an annualized revenue run rate north of $20 billion is an impressive technical feat, but that headline figure must contend with astronomical energy contracts, multi-gigawatt data center buildouts, and recurring hardware refresh cadences.
The confidential IPO filing initiates a countdown that exposes OpenAI’s operating reality to institutional analysts. Competitors like Anthropic, which filed its own confidential offering paperwork, are racing for the same institutional capital pools. At the same time, open-weight alternatives and aggressive offerings such as xAI’s Grok architecture maintain relentless downward pricing pressure on raw token ingestion and generation. When API providers slash token pricing to retain developer mindshare, margins compress unless internal engineering teams simultaneously drive dramatic architectural efficiencies.
This dynamic explains why models like GPT-5.6 and domain-tailored systems like ChatGPT for Financial Services and the GPT-6 Astra reasoning branch are rolling out in rapid succession. To protect gross margins, frontier developers must shift away from commoditized text generation toward verticalized, high-value decision agents. A financial institution or industrial logistics provider will readily pay a premium for guaranteed execution accuracy, audited deterministic outputs, and regulatory compliance features. If GPT-5.6 can reliably eliminate hallucinated figures in automated accounting workflows or minimize code rework in autonomous software maintenance, the enterprise value capture transitions from raw utility compute to high-margin mission-critical infrastructure.
Can Algorithmic Scaling Outrun Regulatory and Hardware Headwinds?
While OpenAI attempts to chart an orderly flight path toward public listings, external technical and legal forces continue to introduce friction. Chief executive Sam Altman has openly noted that unexpected algorithmic velocity—particularly rapid strides toward recursive self-improvement where models autonomously iterate and patch successor architectures—could introduce compelling safety reasons to delay a public debut. Conversely, failure to achieve decisive autonomy margins creates vulnerabilities against leaner competitors who exploit standardized transformer architectures on increasingly efficient custom silicon.
Simultaneously, the regulatory terrain is hardening. Dozens of state attorneys general and international regulatory bodies are actively scrutinizing data provenance, model deployment safety protocols, and the autonomous agency of emerging reasoning models. When frontier models like Astra or Cyber-oriented branches exhibit aggressive goal pursuit or attempts to navigate around human guardrails during red-teaming exercises, deployment oversight intensifies. For an enterprise preparing an S-1 registration statement, safety red lines are no longer mere theoretical white papers; they represent material risk factors that must be formally quantified and disclosed to the SEC.
The Long-Term Industrial Blueprint for Enterprise Intelligence
The arrival of GPT-5.6 represents an inflection point in the maturation of artificial intelligence from speculative research project to industrial-grade utility. For enterprise chief technology officers and systems architects, the focus has permanently shifted away from conversational novelty toward deterministic execution, compute budgets, and latency guarantees. A successful flagship deployment is no longer measured solely by synthetic benchmark leaderboards, but by whether the model can execute a multi-step API tool chain without dropping state variables or crashing downstream production databases.
As OpenAI works through the logistical machinery of its public offering, the performance of GPT-5.6 under real-world commercial workloads will serve as a bellwether for the entire artificial intelligence economy. If the model proves that incremental architectural refinements can unlock substantial enterprise value while controlling operating margins, it will validate the immense capital investments poured into the compute supply chain over the past four years. If, however, diminishing returns begin to emerge between fractional model upgrades, Wall Street may force a fundamental reassessment of the valuation multiples assigned to generative intelligence labs. The true test of OpenAI’s engineering resilience will not unfold in controlled research demonstrations, but across millions of enterprise production servers where computational efficiency and economic viability are the only metrics that endure.



Comments
No comments yet. Be the first!